This is the Second blog in the series of blogs where we will utilizing the full potential of the GPU hardware resources for developing the AI solutions
We established the foundational knowledge for building a GPU-powered AI system. Now, we shift our focus from the “what” to the “how.” How do we as developers actually command this incredible computational power? How do we translate our Python code into massively parallel tasks executed on thousands of GPU cores?
This time we dives into the developer’s ecosystem, focusing on the roles of CUDA and cuDNN, explaining why Python has become the undisputed language of AI, and providing hands-on code examples to get you started.
It might seem counterintuitive that a dynamically-typed, interpreted language like Python is the king of a performance-critical field like AI. The reason is simple: Python offers the perfect balance of developer productivity and high-performance execution.
1. High-Level Abstraction: Python frameworks like PyTorch and TensorFlow provide an incredibly simple API to hide the underlying complexity. A single line of Python, model.to(‘cuda’), triggers a cascade of optimized, low-level C++ and CUDA code that moves your entire neural network to the GPU. You get the performance of C++ without having to write it.
2. The “Glue Language” Paradigm: Python’s “slowness” is irrelevant for AI because the computationally intensive tasks (the matrix multiplications, convolutions, etc.) are not run by the Python interpreter. They are executed by the highly-optimized, pre-compiled backends of the frameworks. Python simply acts as the “glue,” orchestrating these high-performance calls.
3. Unbeatable Ecosystem: The AI/ML ecosystem in Python is unparalleled. Libraries for data manipulation (Pandas, NumPy), model sharing (Hugging Face), computer vision (OpenCV), and experimentation are all built around Python, creating a seamless and powerful development experience.
Let’s see how easy it is to harness the GPU in practice. The following examples use PyTorch, but the concepts are nearly identical in TensorFlow.
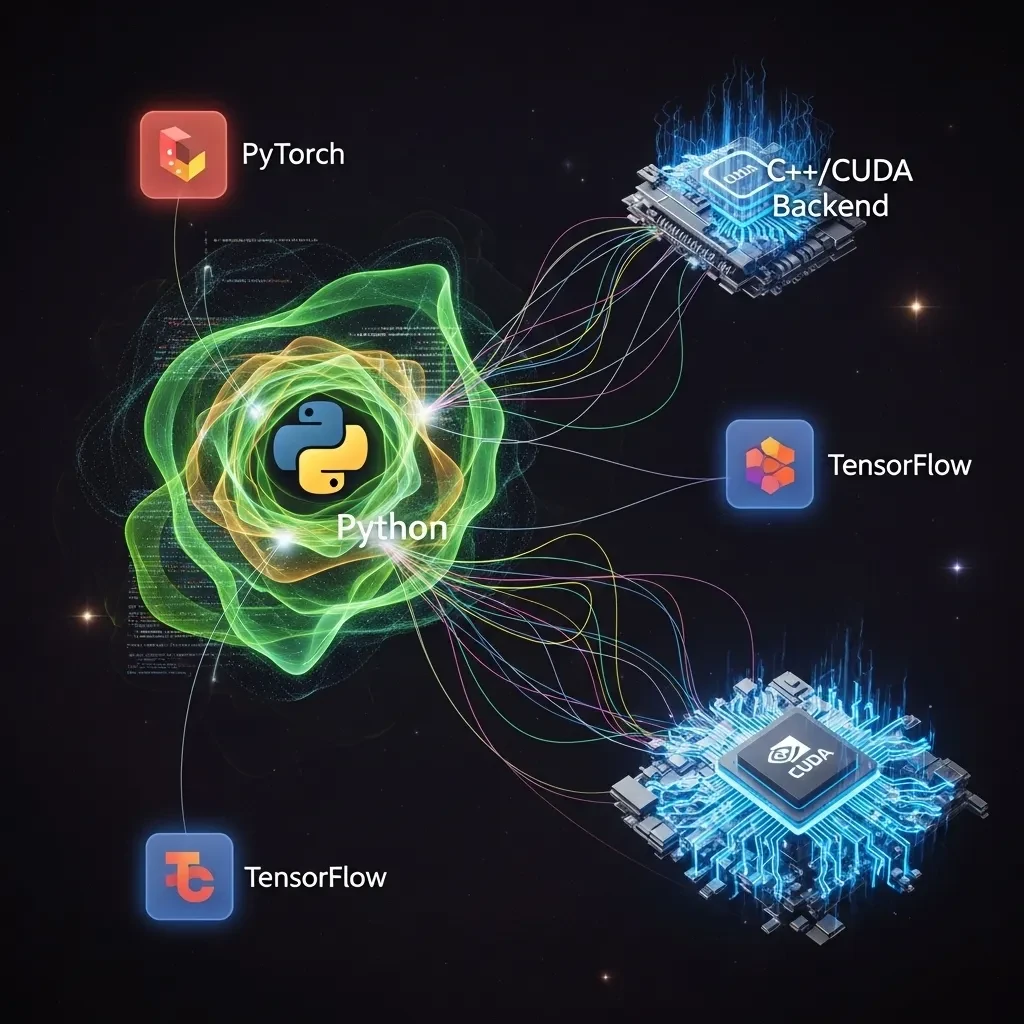
This visual represents how Python acts as the central coordinator. It connects the user-friendly AI libraries like PyTorch and TensorFlow to the powerful, high-performance C++ and CUDA backend where the real number-crunching happens.
First, let’s verify we can access the GPU and move data to it.
Moving a single tensor is simple, but the real power comes from moving your entire model and all its data to the GPU for training. This is exactly how your object detection model would be accelerated.
The same principles apply to today’s most advanced models, where GPU acceleration is not just helpful but absolutely essential.
LLMs have billions of parameters, making them incredibly demanding on memory (VRAM) and compute. Running them requires a GPU.
An AI Agent combines models to perceive, reason, and act. The GPU is the central hub that enables this loop to run in real time. For example, an agent might combine your YOLOv8 detection model with an LLM for decision-making.
The modern AI development stack is a masterpiece of layered abstraction. At the bottom, CUDA provides raw access to the immense power of the GPU. Layered on top, cuDNN offers optimized deep learning primitives. But for most of us, the entry point is Python—a language that provides a simple, elegant interface to this entire ecosystem.
By understanding how these layers interact, you’re not just a user of a framework; you’re a developer who can reason about performance, debug bottlenecks, and truly harness the hardware that drives the entire AI revolution, from simple classifiers to sophisticated, reasoning agents.